Site Reliability Engineering Training Guide for Beginners
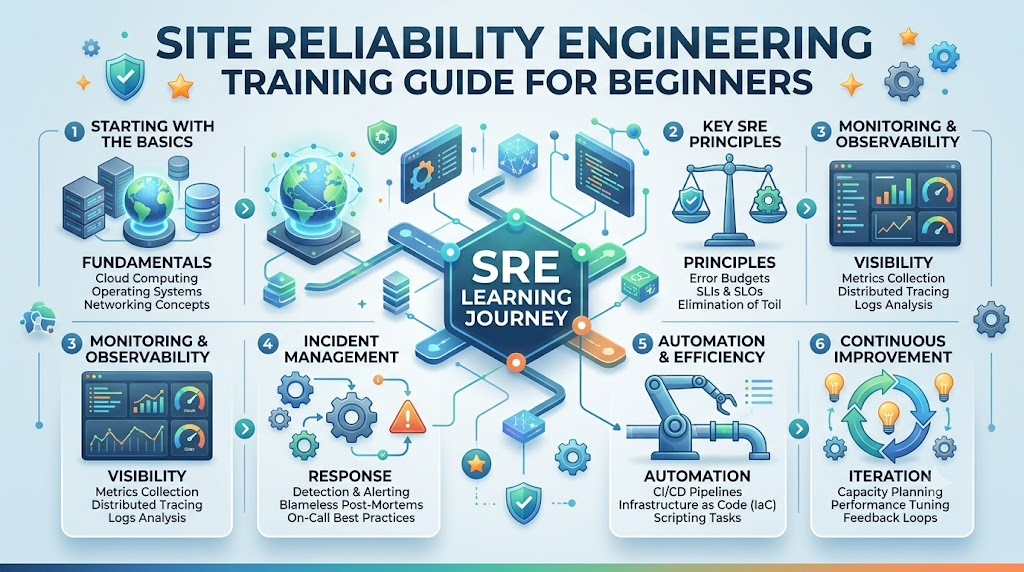
Introduction
Modern apps must work well every day. Users expect fast and steady service. Even small errors can cause problems.
This is where Site Reliability Engineering, or SRE, helps. SRE teams keep systems stable, safe, and easy to manage.
SRE combines software skills with system work. It also uses tools, data, and smart work methods.
An SRE Engineer watches system health and helps fix problems. They also reduce repeat issues through automation.
SRESchool.in helps learners understand these ideas in simple steps. Its learning focus covers cloud systems, automation, monitoring, and reliability.
A good SRE Course can help beginners learn the basics. It can also help working teams improve their skills.
What Does Site Reliability Engineering Mean?
Site Reliability Engineering is a way to keep software systems reliable. It uses software and smart system work to do this.
An SRE team does more than fix broken systems. The team also works to stop problems before they grow.
For example, a website may become slow during busy hours. An SRE team checks the cause and plans a fix.
The team may also add better alerts or automate a task. This saves time and helps reduce human errors.
SRE also uses clear goals. These goals help teams know how well a service works.
SLI, SLO, and SLA in Simple Words
These three terms can sound hard at first. Their basic ideas are quite simple.
An SLI measures service performance. For example, it can measure request speed.
An SLO sets a reliability goal. For example, a team may set a goal for fast responses.
An SLA is an agreement about service quality. It can define what users can expect from a service.
An error budget shows how much failure a service can allow. Teams can use this idea when planning new changes.
Why Reliability Matters
A reliable system gives users a better experience. It also helps teams spend less time fixing repeat problems.
Good reliability does not mean zero errors. Every system can face failures.
The goal is to control failures and recover quickly. Teams also learn from each incident.
Key Skills Every SRE Engineer Needs
An SRE Engineer needs many skills. These skills often grow through practice and real system work.
Linux, cloud systems, networks, coding, and automation are useful areas. Monitoring and incident response also play a major role.
A learner does not need to master everything at once. A clear learning path can make the process easier.
Monitoring and Observability
Monitoring means watching a system for known problems. It can track things like errors, traffic, and system load.
Observability goes one step further. It helps teams understand why a problem may be happening.
For example, an app may become slow. Logs, metrics, and traces can help find the cause.
Good SRE Tools can make this work easier. Teams can collect data and set alerts for key problems.
Automation and Incident Response
SRE teams often automate repeat tasks. Automation can save time and reduce manual mistakes.
Incident response is the process of handling system problems. Teams need clear steps for alerts and service failures.
A good response starts with finding the problem. The team then works to restore the service.
After that, the team can study the cause. This helps prevent the same problem later.
SRE Best Practices for Reliable Systems
SRE Best Practices help teams build better work habits. They also make system care more clear and repeatable.
One useful practice is to set clear reliability goals. Teams should know what good service looks like.
Another practice is to use alerts with care. Too many alerts can make it hard to spot real problems.
Teams should also review major incidents. The goal is to learn and improve, not blame people.
Use Data to Make Better Choices
SRE teams need useful data. Data can show where systems fail or slow down.
Metrics can show traffic and error levels. Logs can show events and useful system details.
Traces can show how a request moves through different services. Together, these tools give teams a clearer view.
| SRE Area | Simple Meaning | Common Use |
|---|---|---|
| Monitoring | Watching system health | Find known issues |
| Observability | Understanding system behavior | Find root causes |
| Automation | Letting tools do repeat work | Save time |
| Incident response | Handling service problems | Restore service |
| Capacity planning | Planning system resources | Handle growth |
Plan for System Growth
A system may work well with low traffic. It may struggle when many users arrive.
Capacity planning helps teams prepare for higher demand. Teams can check CPU, memory, storage, and network use.
They can also review past traffic patterns. This helps them plan resources before problems appear.
Good planning can reduce sudden service issues. It also helps teams use resources in a smart way.
How SRE Training Can Build Practical Skills
SRE Training can help learners follow a clear learning path. It can start with basic ideas and move toward real system work.
A good SRE Tutorial can explain each topic with simple examples. Learners can then practice the same ideas in labs.
SRE Certification may also help learners study key reliability topics. However, real skill comes from learning and practice.
What Can an SRE Course Cover?
An SRE Course can cover many useful areas. The exact content can differ between learning programs.
| Learning Area | What Learners Can Practice |
|---|---|
| SRE basics | Core reliability ideas |
| Cloud systems | Running and managing services |
| Monitoring | Tracking system health |
| Kubernetes | Managing container systems |
| Terraform | Setting up infrastructure with code |
| Incident management | Handling service problems |
| Automation | Reducing repeat manual work |
| Reliability goals | Using SLI and SLO ideas |
Site Reliability Engineering Training can also connect theory with daily work. Learners can study how teams monitor, fix, and improve services.
SRESchool.in focuses on these core SRE areas. Its learning resources can help beginners understand complex topics in simple steps.
Building a Simple SRE Learning Path
Beginners often wonder where they should start. A simple path can make learning less confusing.
Start with Linux and basic networking. Next, learn cloud and software basics.
Then study monitoring, logging, and alerting. After that, learn incident response and automation.
You can later explore Kubernetes and infrastructure tools. Practice each skill with small tasks.
Learn by Solving Small Problems
Small projects can make SRE concepts easier to understand. For example, create a simple service and monitor it.
Set an alert for high error rates. Then test what happens when the service fails.
Next, write a simple recovery task. Review the event and record what you learned.
This type of practice can build useful habits. It also shows how SRE ideas work in real systems.
Frequently Asked Questions About SRESchool
1. What is SRE?
SRE means Site Reliability Engineering. It helps teams keep software systems reliable. SRE uses software, automation, monitoring, and system skills. It also helps teams manage incidents and reduce repeat problems.
2. What does an SRE Engineer do?
An SRE Engineer helps keep services stable and reliable. They monitor systems and respond to incidents. They also automate repeat work and improve system design. Their work can involve cloud systems, code, networks, and monitoring tools.
3. What is SRE Training?
SRE Training teaches the main ideas and skills used in reliability work. It can cover monitoring, SLOs, incident response, automation, cloud systems, and capacity planning. Practical training can also help learners understand how these skills work together.
4. Is an SRE Course useful for beginners?
Yes, an SRE Course can help beginners learn in a clear order. A good course should explain basic ideas before advanced topics. Beginners can start with Linux, cloud basics, monitoring, and automation. Practice can then build stronger skills.
5. What is SRE Certification?
SRE Certification is a formal way to show knowledge of SRE concepts. Certification programs can cover reliability goals, monitoring, incidents, and automation. Learners should also gain practical skills. Certification alone does not replace real practice.
6. What are SRE Tools?
SRE Tools help teams monitor and manage systems. They can support logs, metrics, alerts, cloud work, deployment, and automation. The right tool depends on the system and team needs. Tools should solve real problems instead of adding extra work.
7. What is an SLO?
An SLO is a reliability goal for a service. It tells a team what level of service it wants to provide. For example, a team may set a goal for request success. SLOs help teams make clear reliability choices.
8. What is an error budget?
An error budget is the amount of failure a service can allow. It connects reliability with change work. When a service has used too much of its budget, teams may slow risky changes. This helps balance speed and reliability.
9. What can I learn through an SRE Tutorial?
An SRE Tutorial can teach core ideas in small steps. Topics may include monitoring, SLOs, cloud systems, Kubernetes, automation, and incident response. Simple tutorials can help beginners understand how each part works in practice.
10. Is SRE Training in India useful for learners?
SRE Training in India can help learners build skills for modern system work. Learners can study cloud systems, automation, monitoring, and reliability. The value depends on the course content and practice. Learners should choose training that matches their goals.
Final Thoughts
SRE helps teams keep software systems reliable and easier to manage. It combines software skills with system care, automation, and clear goals.
Beginners can start with simple concepts. Linux, cloud systems, monitoring, and basic automation are useful first steps.
Next, learners can study SLOs, incident response, Kubernetes, and other tools. Practice can help turn these ideas into real skills.
SRESchool.in can be a useful learning resource for people exploring SRE. The main goal should always be clear learning, regular practice, and better system reliability.
Leave a Reply